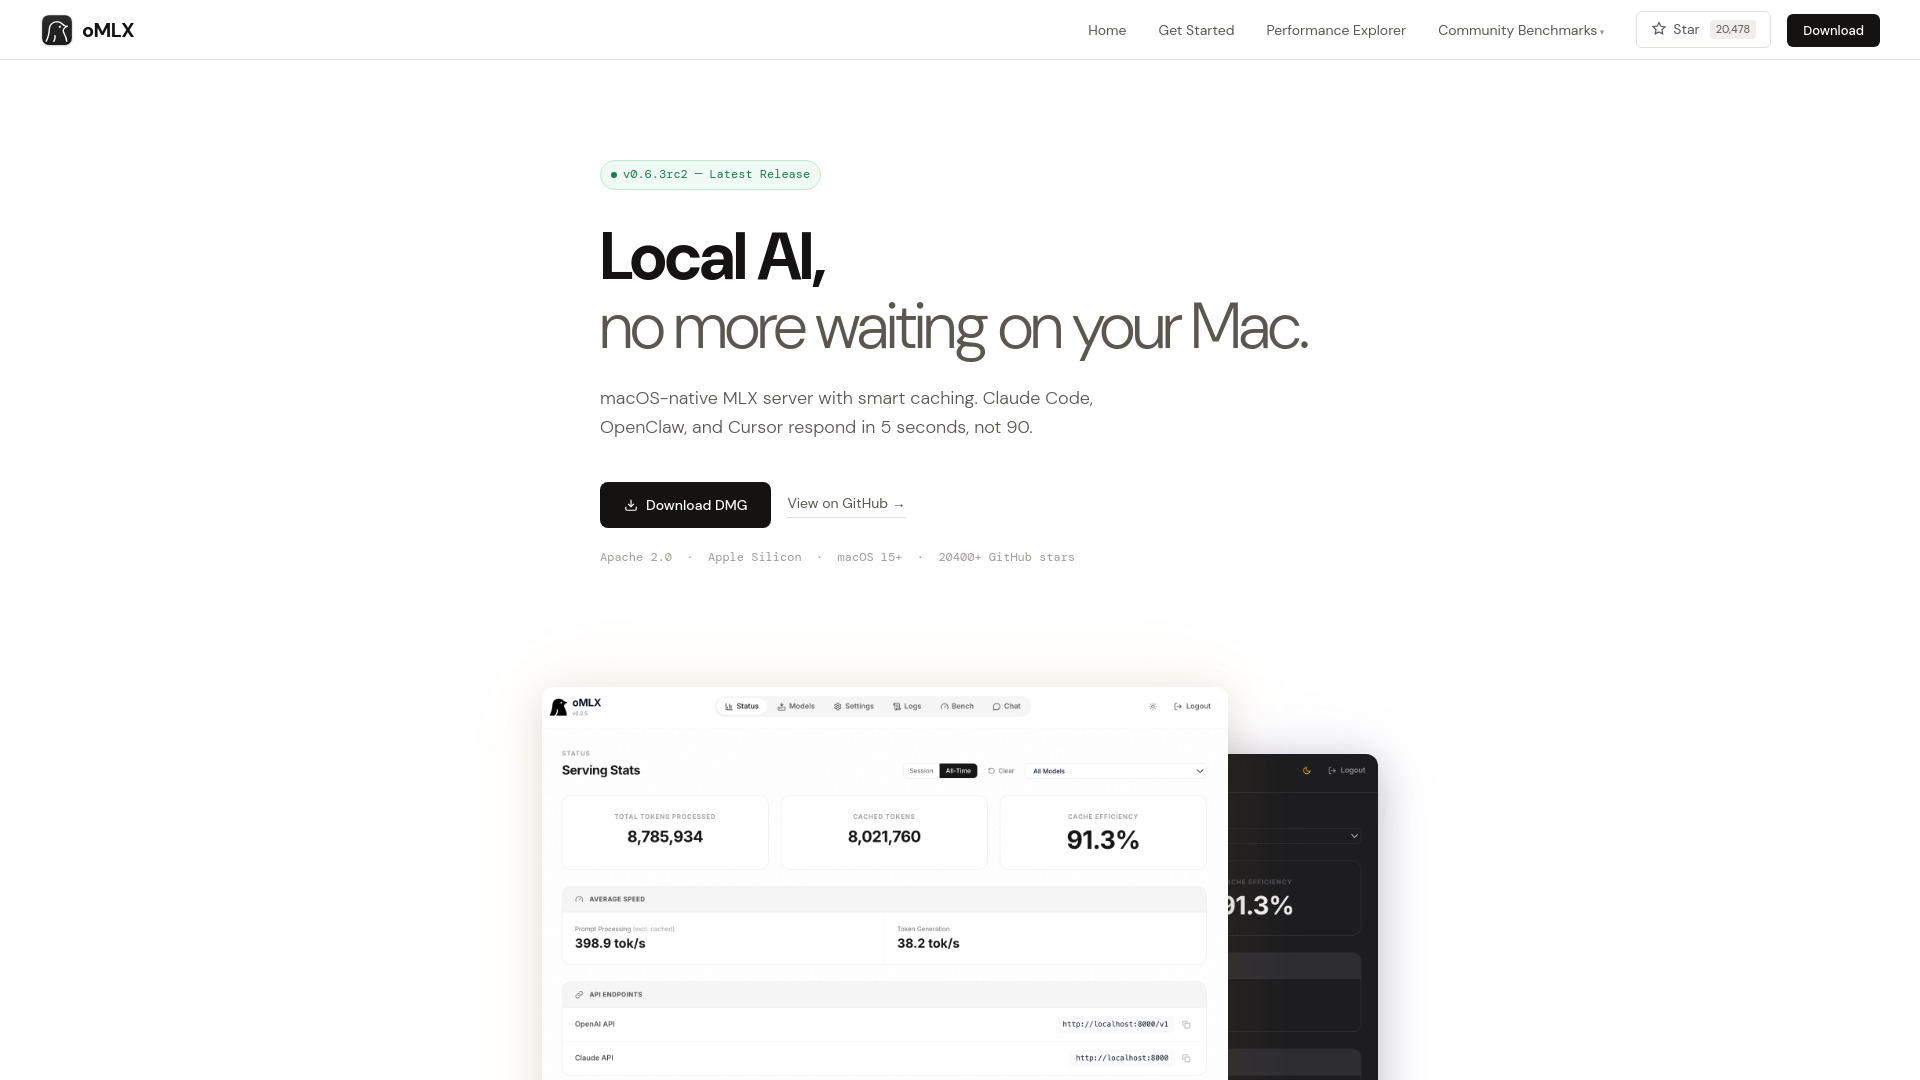
oMLX is a native macOS inference server that lets you run AI models locally on Apple Silicon, powered by Apple's MLX framework. Instead of sending your data to the cloud, you get fast, private inference right on your own machine.
Waiting for the first token can slow down coding agents, so oMLX includes paged SSD KV caching to cut time-to-first-token and keep your workflows responsive. Continuous batching boosts throughput when handling multiple requests, making it well suited for demanding local setups.
Connecting your tools is simple thanks to OpenAI- and Anthropic-compatible APIs, so existing integrations work with minimal changes. oMLX supports LLM, vision-language, embedding, and reranker models, and handles tool calling, MCP integration, and multi-model serving from one place.
A native menu bar application with a web dashboard keeps everything within reach, letting you manage models and monitor serving without leaving your desktop.
Subscribe to get the latest oMLX and global AI updates.


Comments
Loading comments…